Reinforcement Learning Exercise
Implementations of various reinforcement learning algorithms including MDPs, Q-Learning, and Policy Gradients for custom environments.
Key Features
What the system does.
Markov Decision Processes (Lab 1)
Concepts: Fundamental Tabular Methods, MDPs, Value Functions, Value Iteration, and Model-Free RL (such as Tabular Q-Learning). Application: Agents learning to navigate grid worlds and play Pacman using basic tabular methods.
Function Approximation (Lab 2)
Concepts: Linear Function Approximation, LSTD, and Deep Q-Networks. Application: Scaling up RL to handle larger state spaces where tabular methods are no longer feasible by using neural networks or feature extractors.
Policy Gradients (Lab 3)
Concepts: Policy Gradient Methods, Actor-Critic Architectures, Natural Gradients, and Model-Based Exploration. Application: Training agents in environments with continuous action spaces (like controlling a pendulum).
POMDP and Multi-Agent RL (Lab 4)
Concepts: POMDPs, Belief MDPs, Deep RL for POMDPs, and Cooperative MARL algorithms. Application: Dealing with uncertainty when the environment is not fully observable and coordinating multiple agents.
Performance Graphs
Visualisations of model performance and results across experiments.
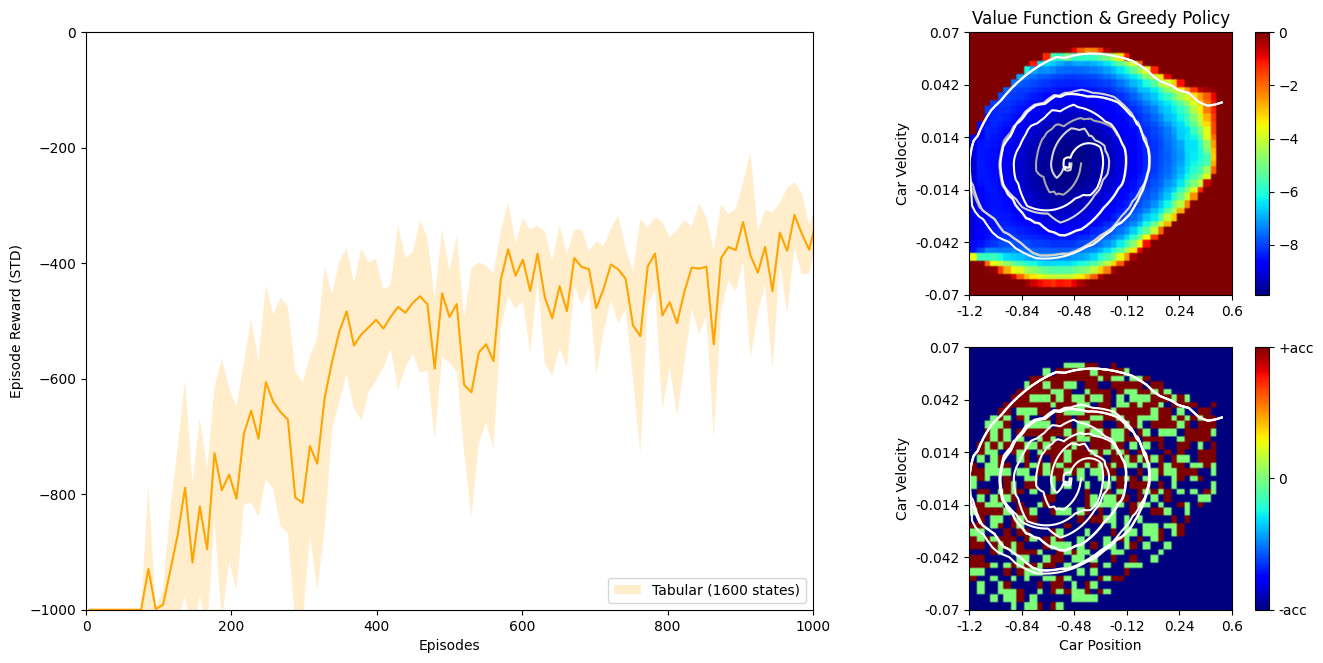
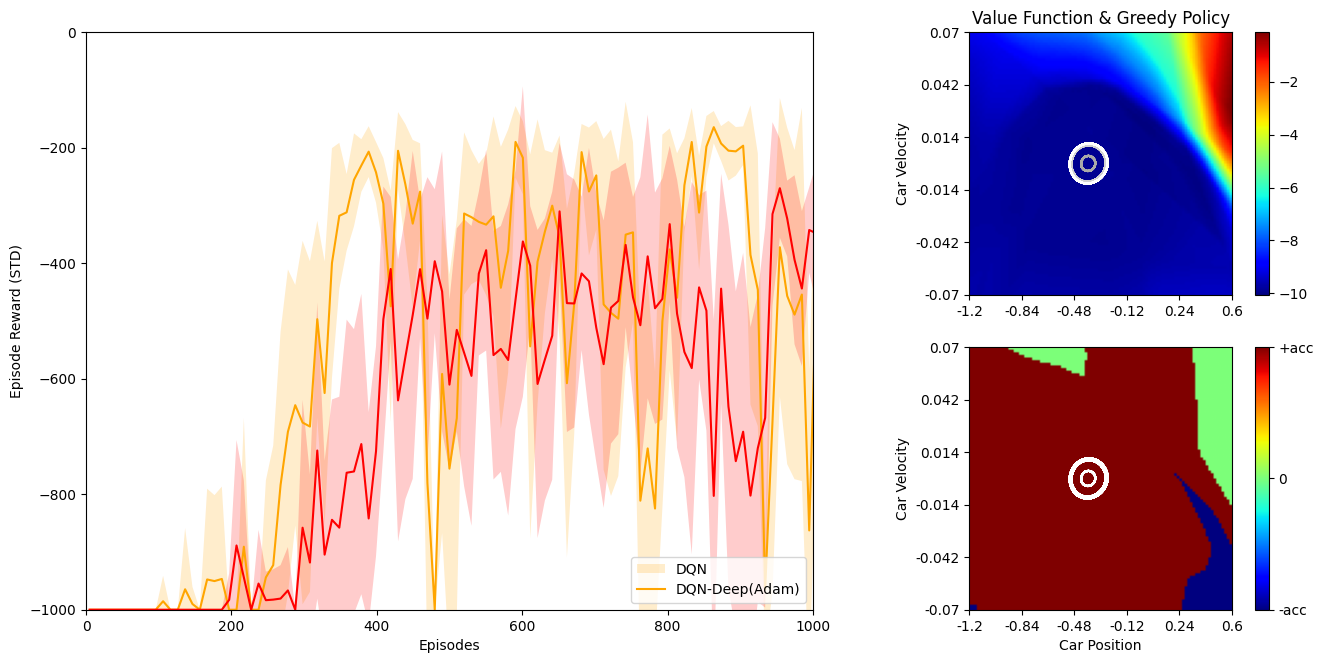
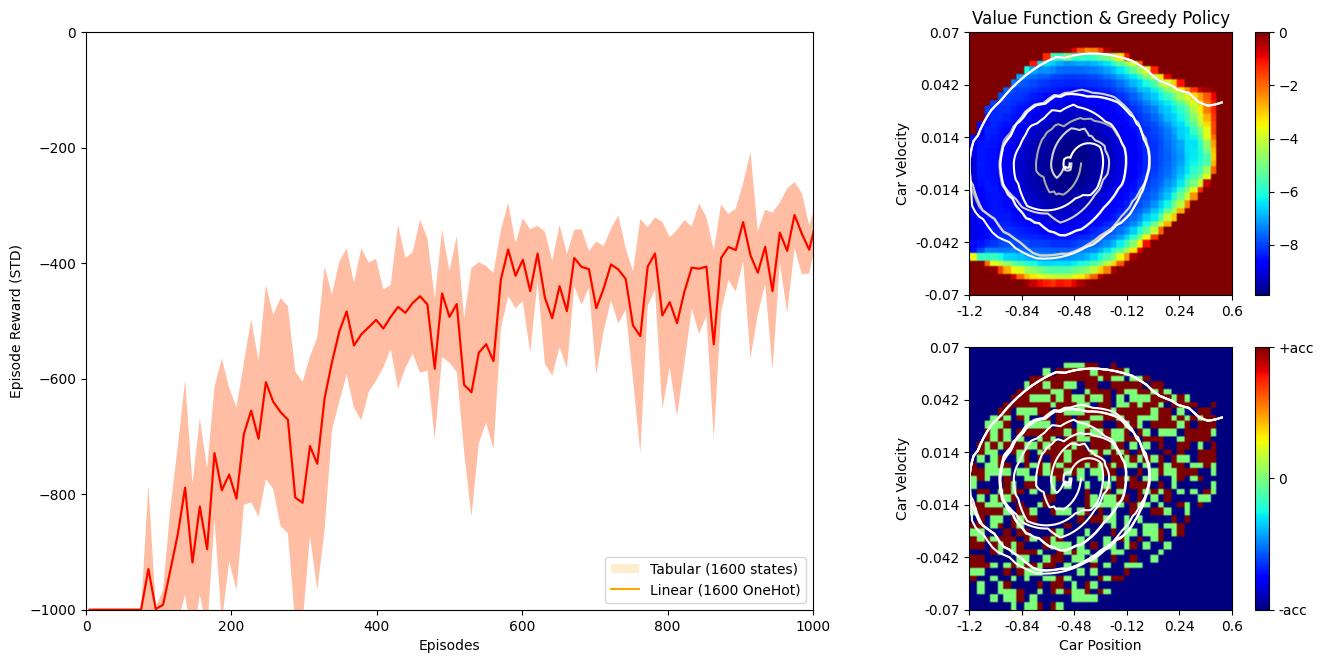
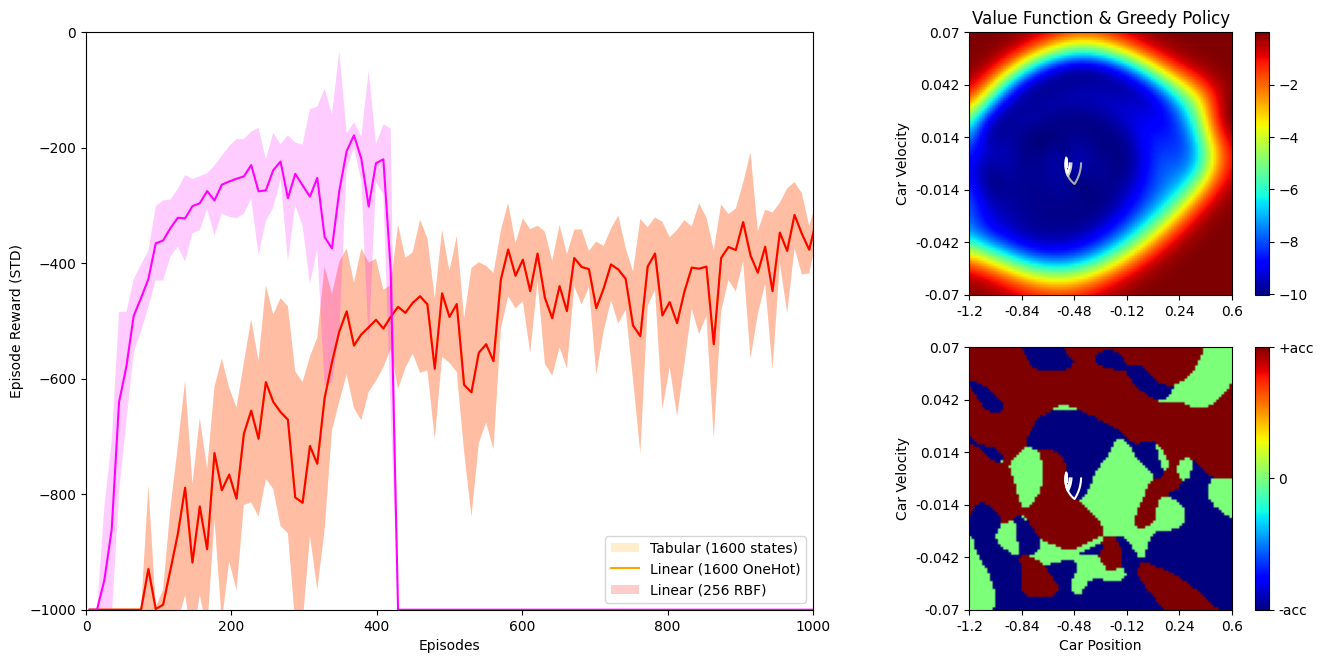
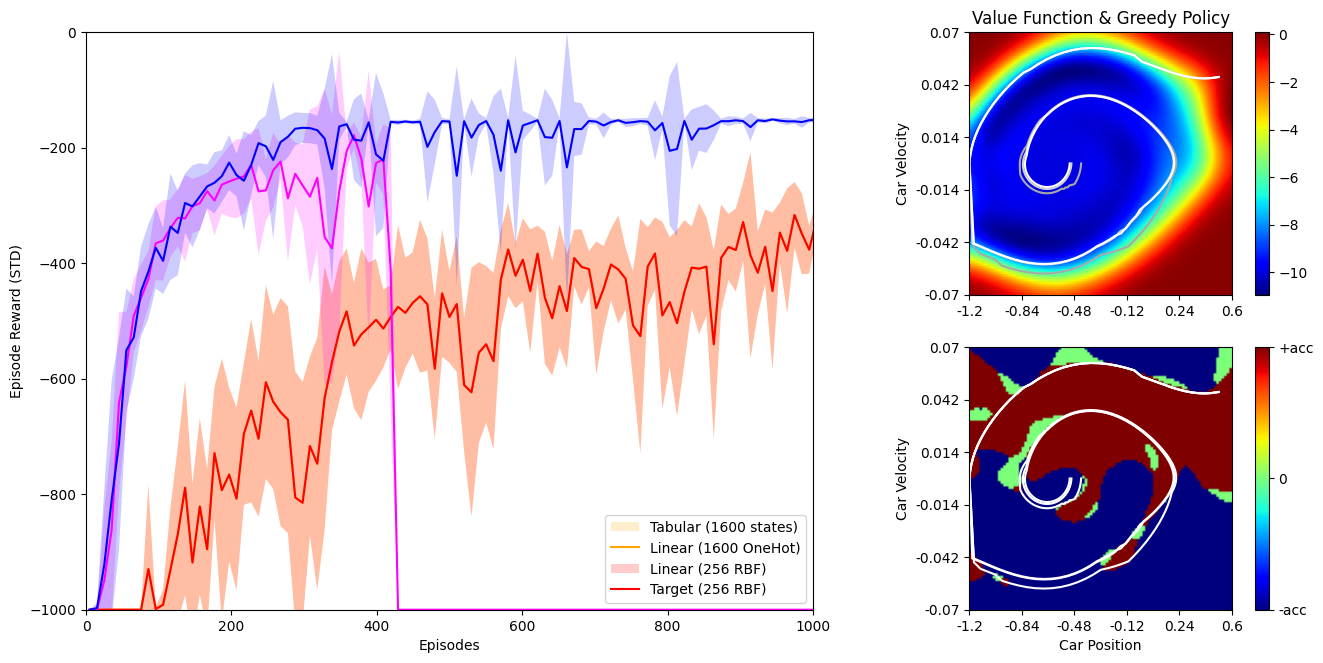
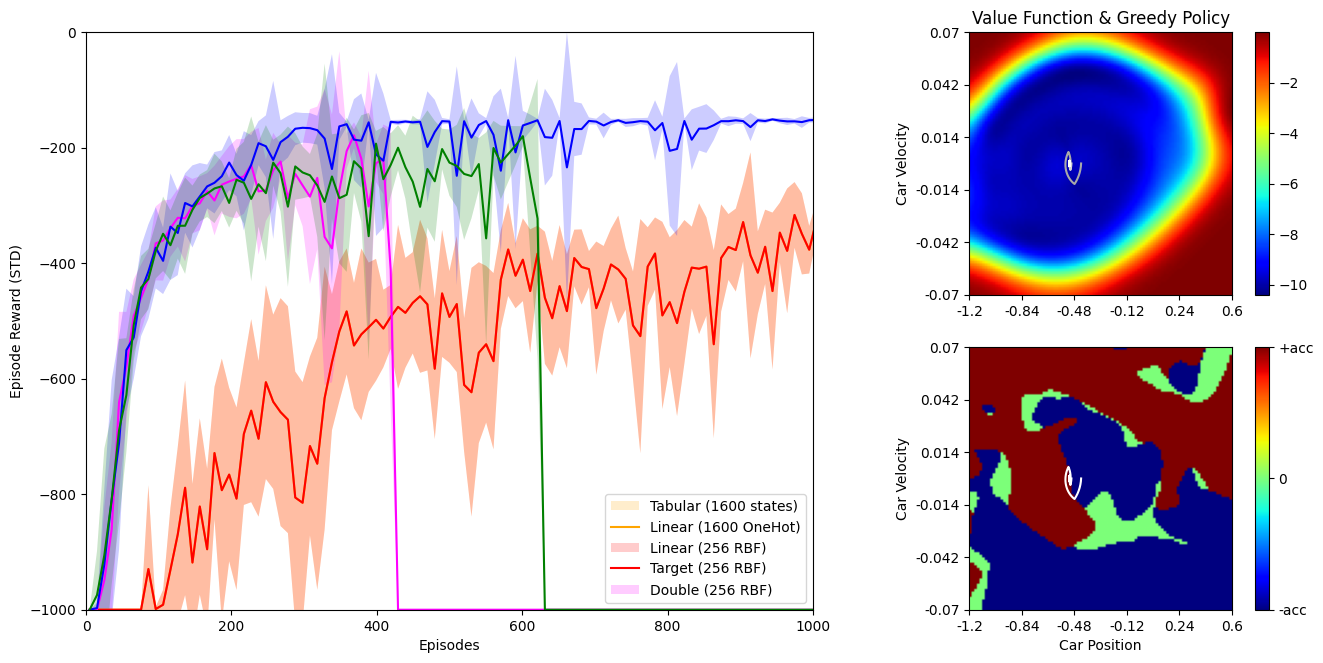
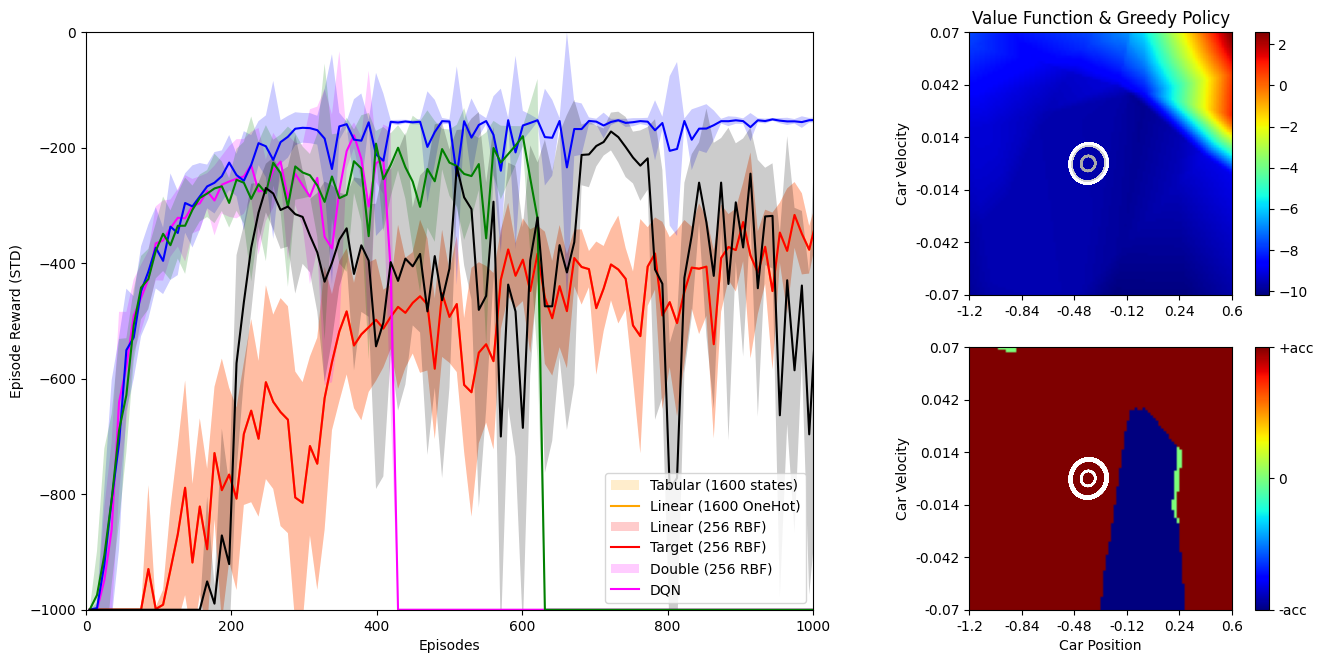
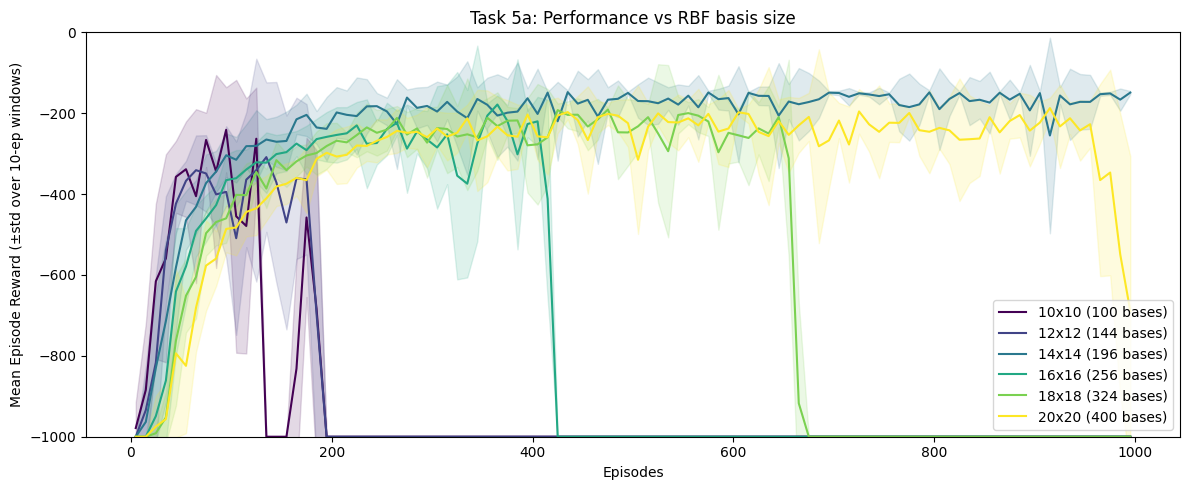
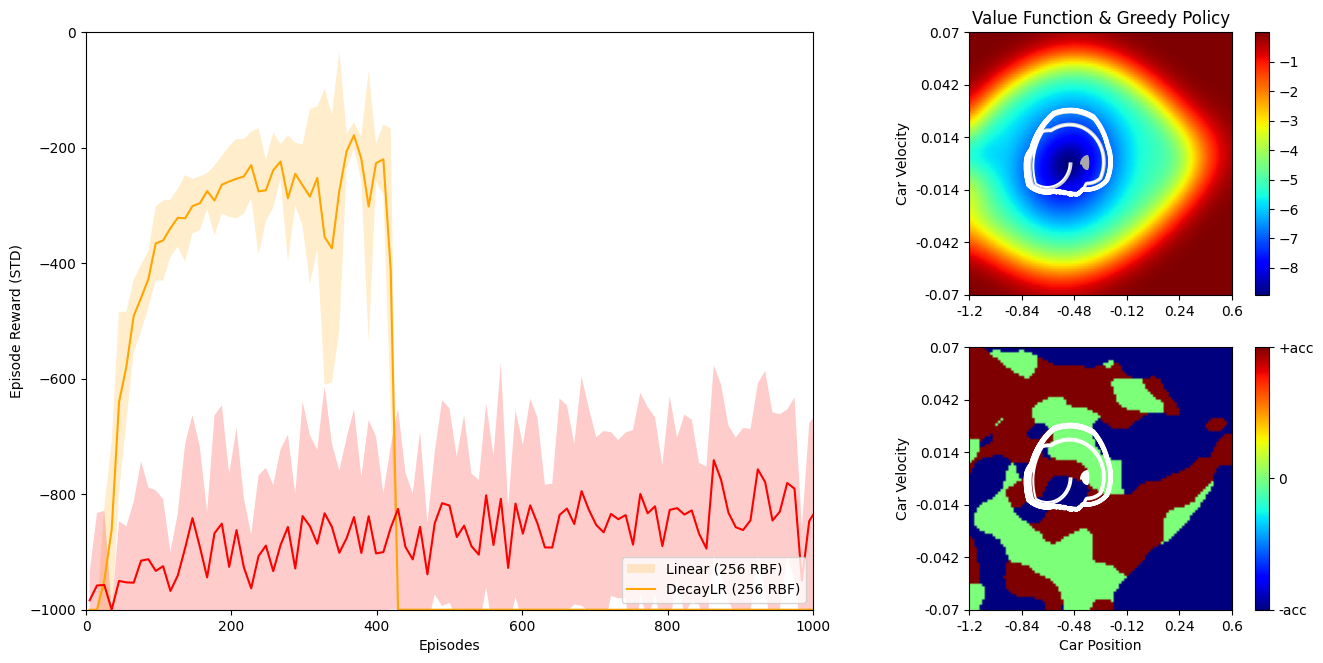
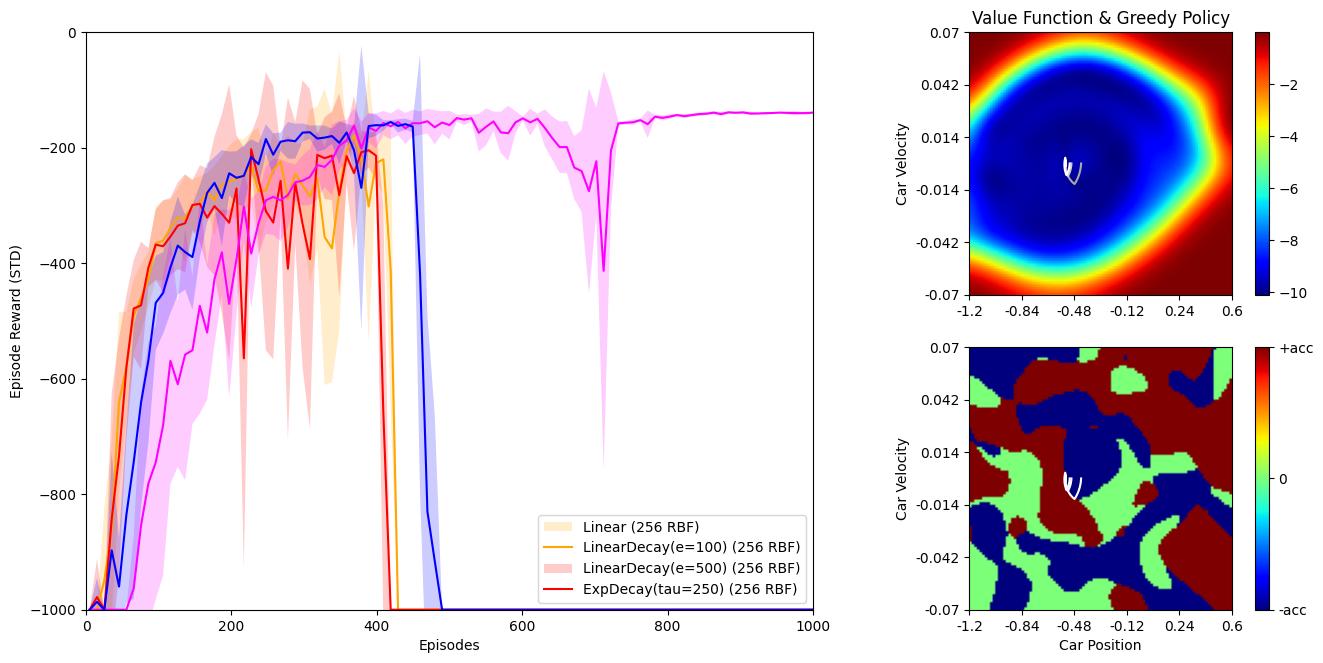
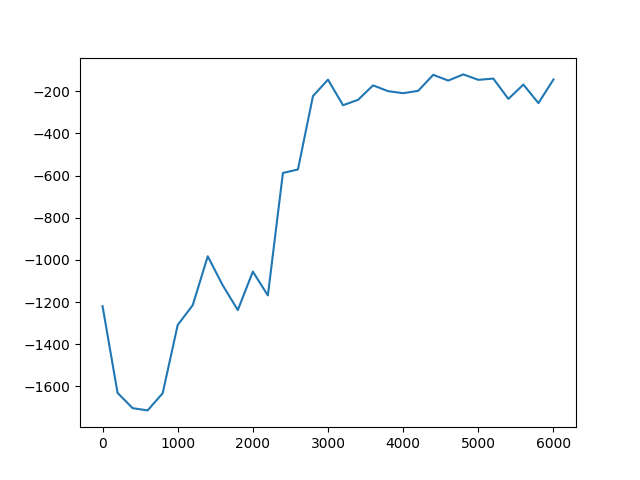
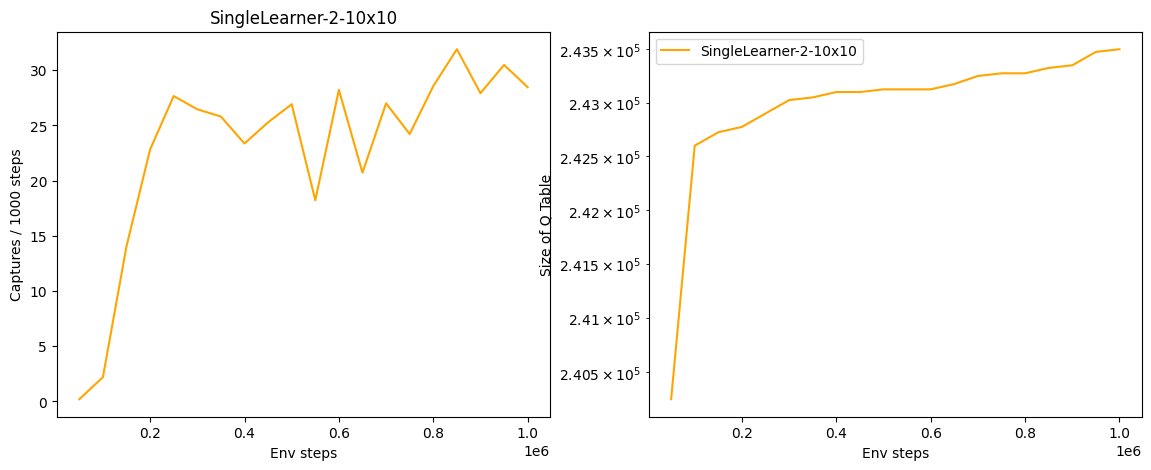
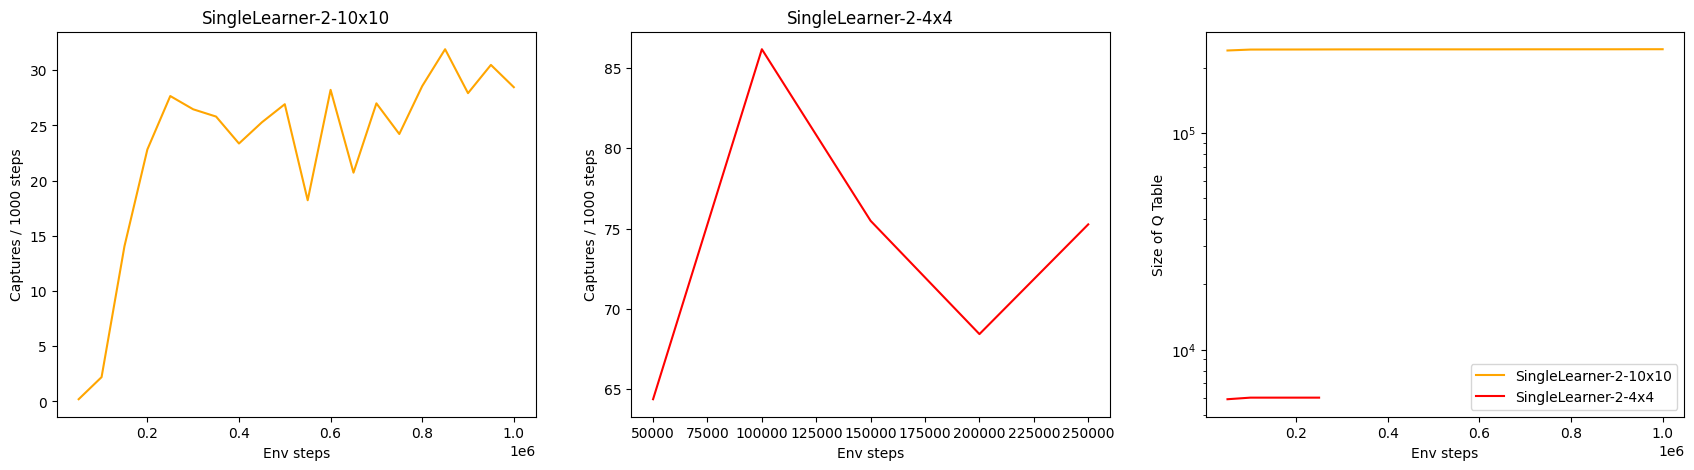
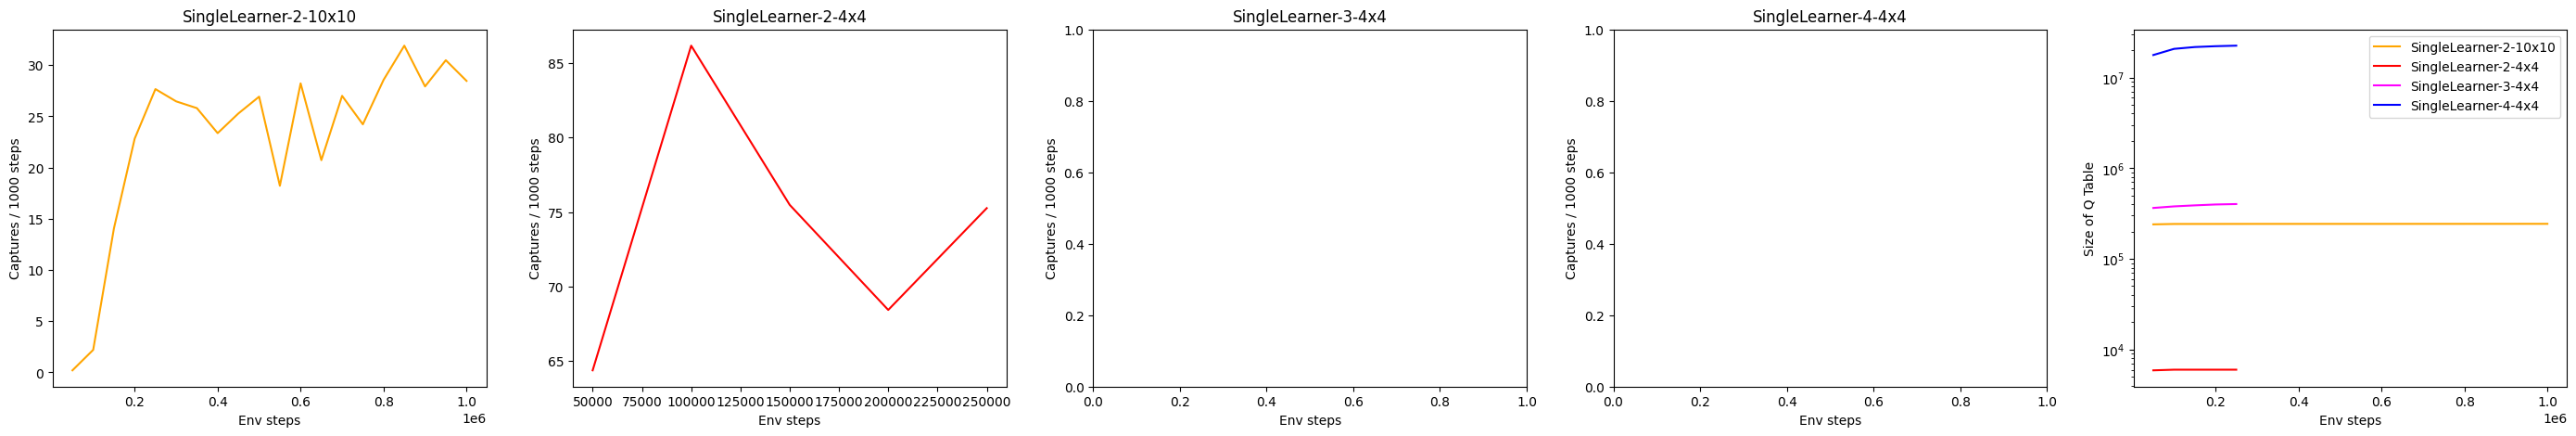
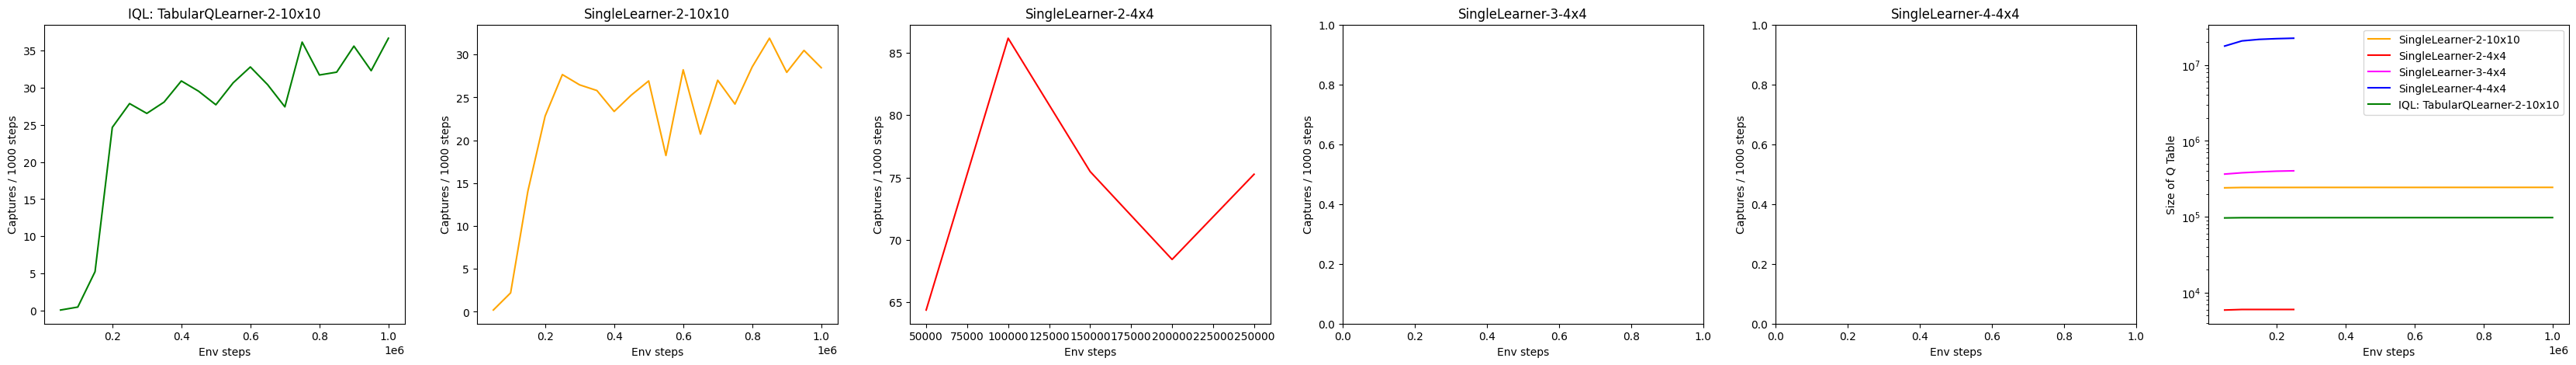
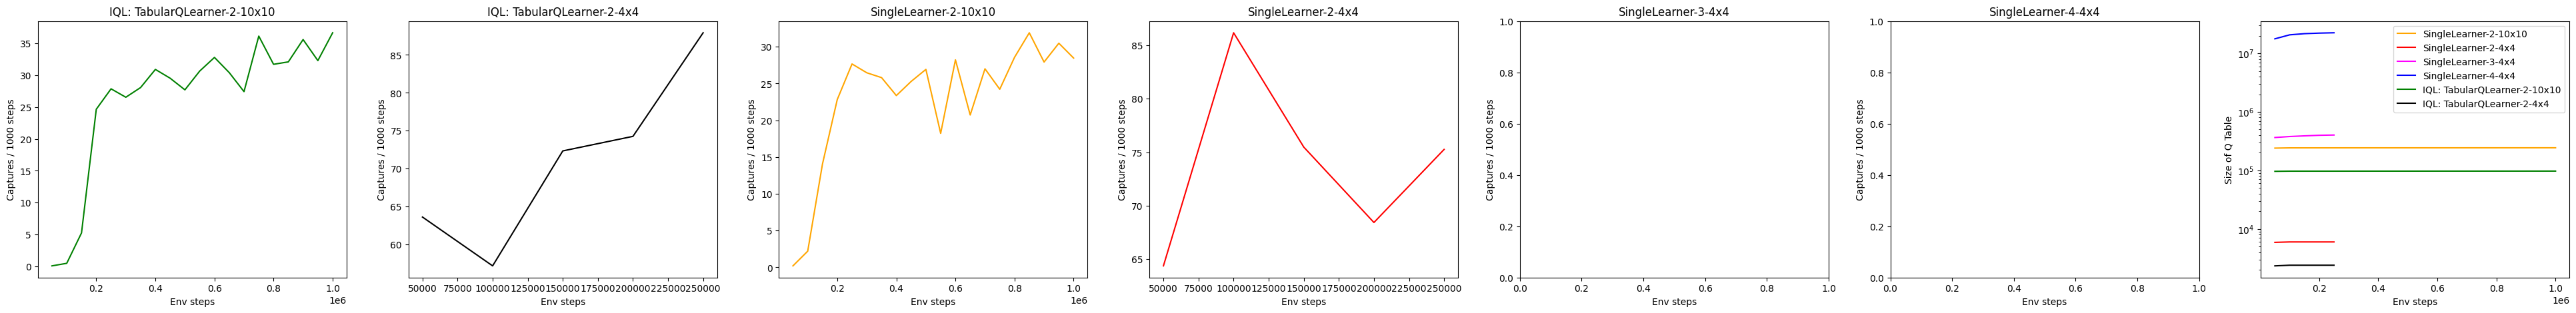

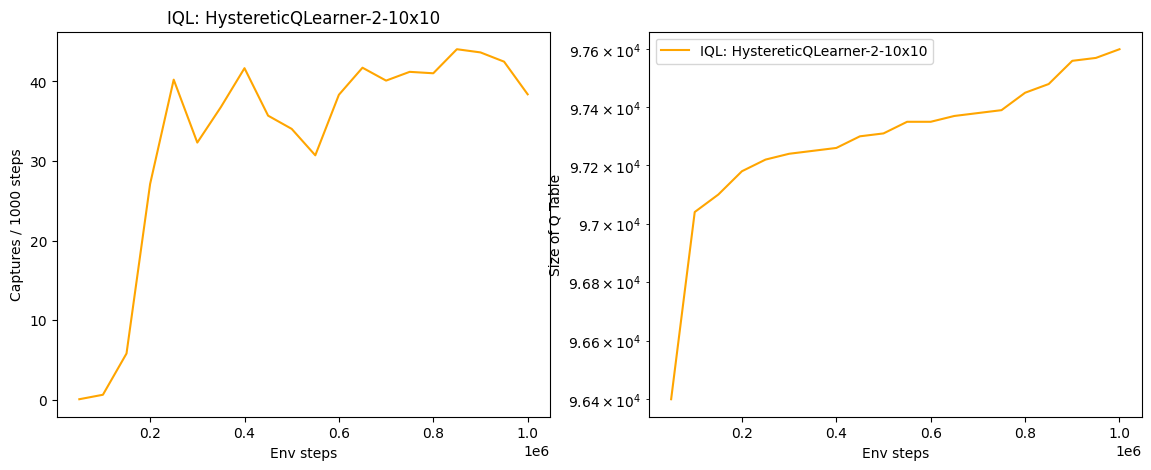
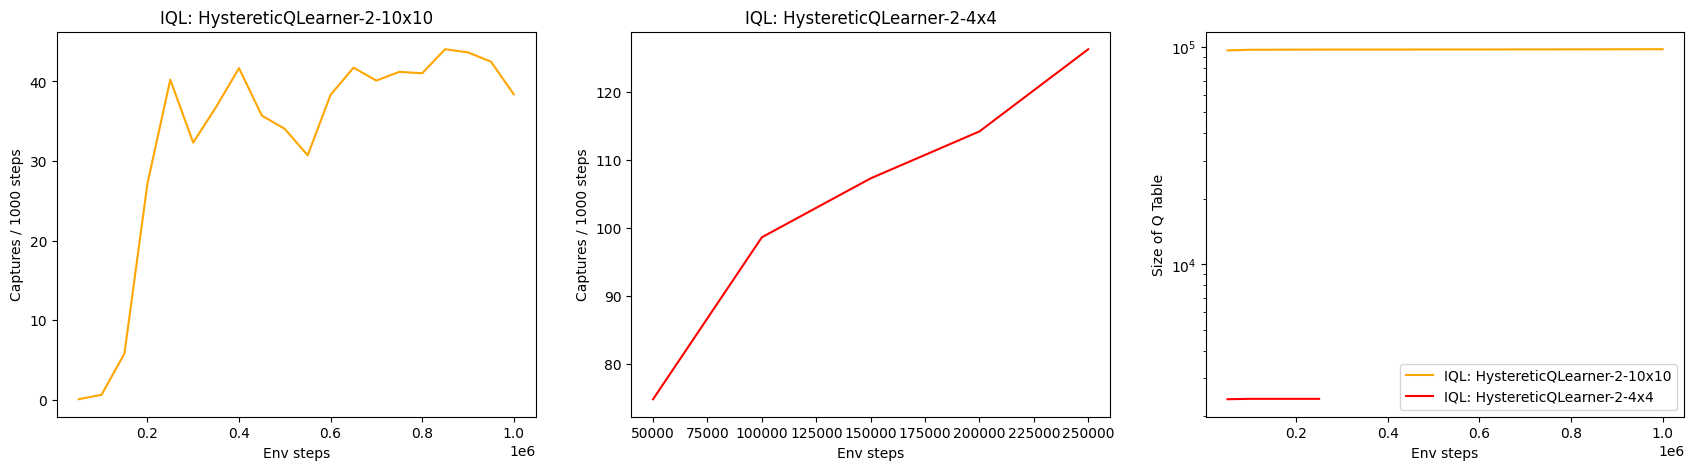
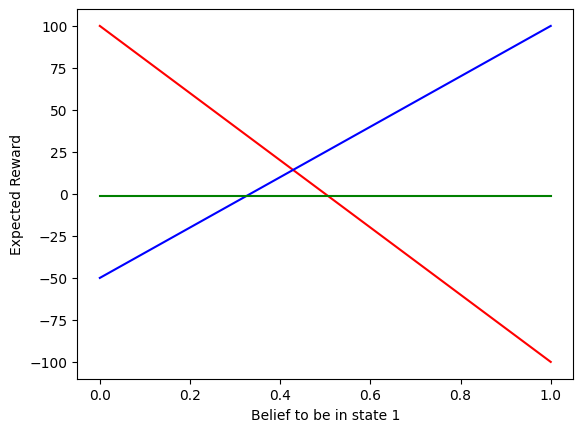
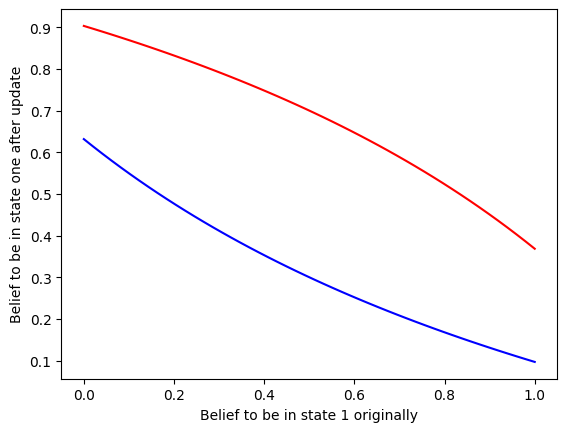
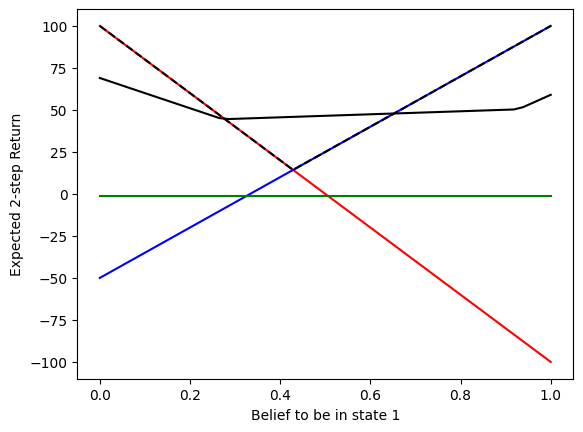
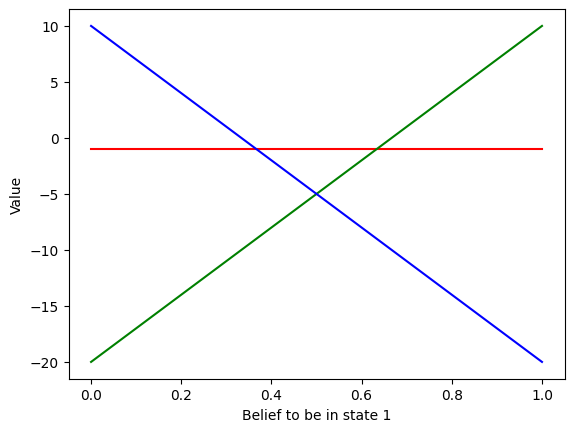
Function Approximation img 1
Performance graph for Function Approximation img 1
Live Simulation Output
Simulated console execution.
Source Code
GitHub repositories for this project.